Split routing: a new architecture for business language models
Commercial limits of monolithic language models
Integrating one large, monolithic model into business processes is losing economic appeal. Selling access to a single superintelligence is becoming a less attractive high-margin B2B proposition.
By 2026, base language models have become more similar in quality while token prices have fallen. Price competition and open-source development reduce the value of raw generation alone, challenging models based on selling flagship access.
Using one model, especially a flagship, for 100% of traffic often means disproportionate costs for small accuracy improvements. Better benchmark scores do not necessarily translate into measurable business value. For enterprise users, choosing a single best model for every request can therefore be an engineering mistake.
Businesses need controlled costs and consistent quality across the system, rather than maximum accuracy on every individual request. Monolithic models often limit flexibility, task-specific adaptation and cost-efficient scaling, all important for marketing and other functions.
Split routing: architecture and principles
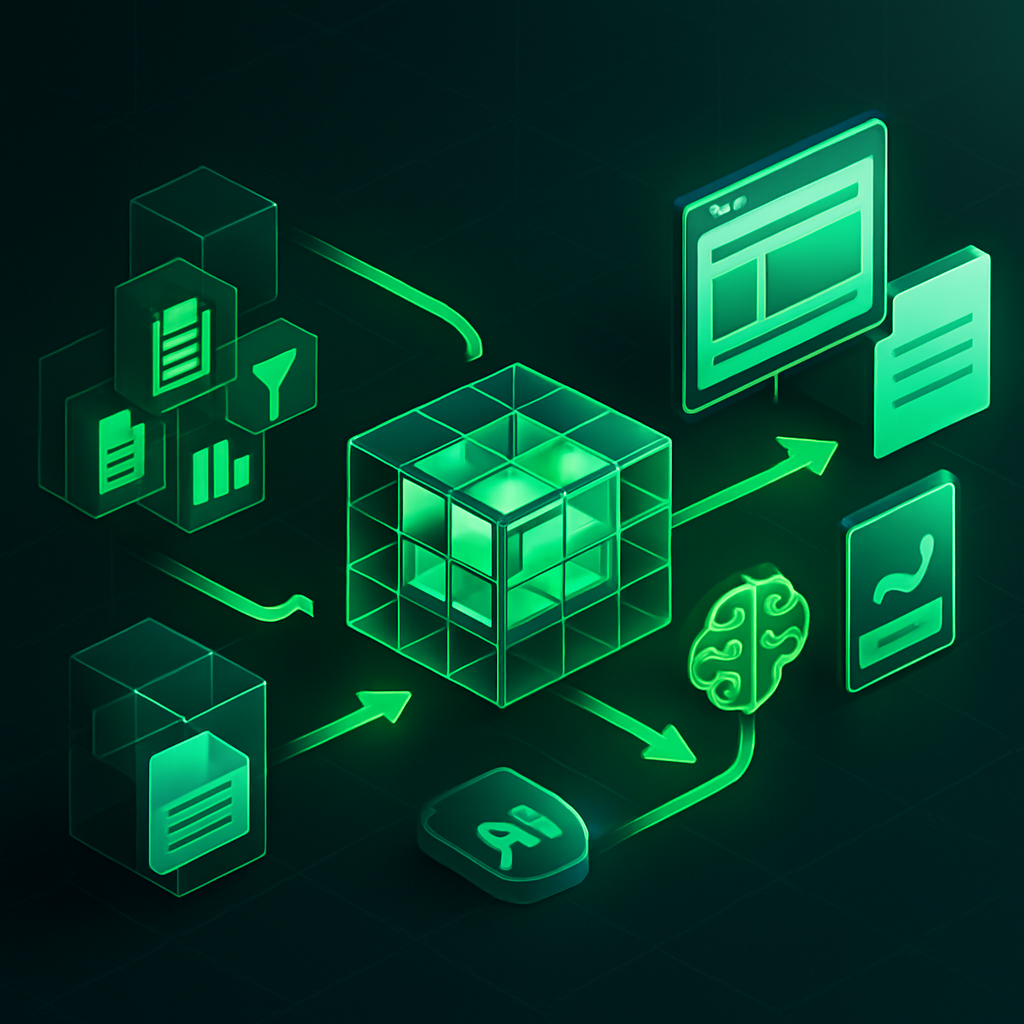
Split routing uses an initial classification layer to distribute requests among language models. It balances performance and processing cost to use resources more efficiently.
The system centres on a request intent and complexity classifier. It quickly directs around 80% of requests to smaller, cheaper models and the most complex or important 20% to larger frontier models. This saves resources without compromising complex cases.
Requests are managed through an end-to-end orchestrator rather than a single API. This makes workflows and model integration more flexible. Prompt adapters format requests for each model, improving consistency and accuracy.
Cascading frameworks such as RouteLLM illustrate this approach. They can retain up to 98% of flagship model accuracy while reducing operating costs by up to 70%, through intelligent workload distribution and optimised processing chains.
Split routing combines quality and efficiency in a cost-effective, scalable approach to language models for integrated digital marketing and automation.
Enterprise economics of split routing
With SaaS services handling millions of monthly requests, processing costs matter. Token prices have fallen many times over, yet the cost difference between model classes can still be tens of times. This creates significant scope for optimisation.
Consider a SaaS service handling 10 million requests each month. Processing every request with an expensive model can push operating costs high enough to make unit economics negative. Split routing sends most requests to cheaper models and only a small share to highly accurate flagship models, substantially reducing costs.
The figures show approximately 74% savings while retaining around 96% of processing quality. Sensible trade-offs and workload architecture achieve this without a substantial accuracy loss.
Split routing can help enterprise customers reduce operating costs by tens of thousands of dollars each month, improve the economics of marketing and product investment, and maintain a consistent user experience. Moving away from always using expensive models supports sustainable, scalable SaaS growth.
Split routing: technical challenges and implementation advice
Multi-model split routing adds infrastructure complexity. Careful engineering oversight is needed to distribute work and maintain service quality.
A classifier assesses each request and chooses the most suitable model. Although classification adds processing overhead, more efficient resource use can reduce median latency by a factor of 2-3.
Prompt drift can reduce split-routing quality. Replace free-form inputs with strict schemas and automatic typing to make model inputs more stable and predictable.
Debugging and monitoring a complex system require end-to-end request tracing with unique identifiers. Following requests through the orchestrator and classifier reveals bottlenecks and helps resolve errors quickly.
Introduce split routing gradually. Configure and train the classifier in stages to reduce risks without interrupting operations.
In this architecture, the model becomes a resource rather than the final product. Profitability and efficiency depend on distributing and orchestrating work across models, requiring different management tools and processes.